Toward Physical Super Intelligence피지컬 슈퍼 인텔리전스를 향하여
Robotics research toward Physical Super Intelligence: vision-language-action (VLA) models, world models, agentic robotics, embodied intelligence and humanoid robot intelligence, including 3D VLM-based embodied AI for mobile bimanual manipulation and LiDAR sensing for physical AI.피지컬 슈퍼 인텔리전스를 향한 로보틱스 연구: 비전-언어-행동(VLA) 모델, 월드 모델, 에이전틱 로보틱스, 체화 지능, 휴머노이드 로봇 지능. 모바일 양팔 매니퓰레이션을 위한 3D VLM 기반 embodied AI와 피지컬 AI용 라이다 센싱을 포함.
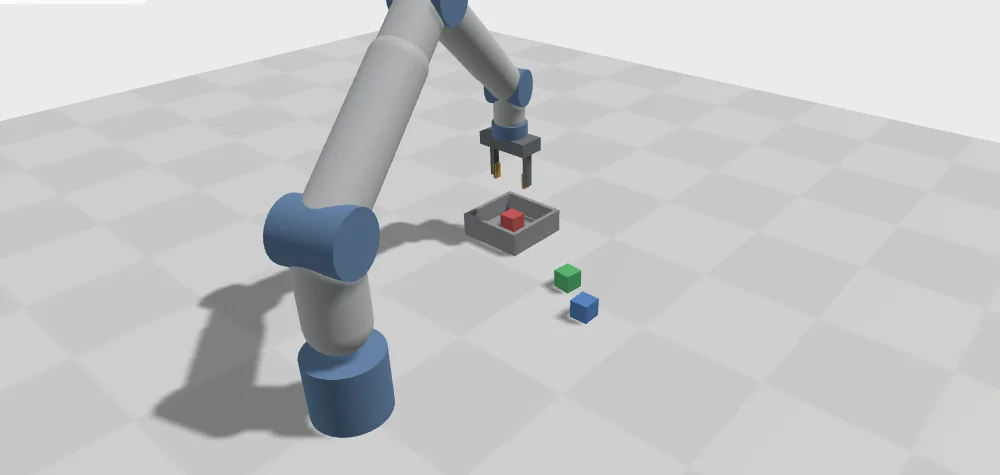
VLA-style rollout on a 7-DOF Franka Panda7자유도 Franka Panda의 VLA 방식 실행
A Franka Panda arm carries out LIBERO-style language instructions in MuJoCo 3.14.0, running entirely in your browser. The task is executed in action chunks through inverse kinematics and impedance control, so you can see how the chunk horizon and perception noise change the motion.Franka Panda 로봇팔이 LIBERO 방식의 언어 지시를 MuJoCo 3.14.0에서 수행하며, 모든 계산은 브라우저 안에서 이루어집니다. 작업은 역기구학과 임피던스 제어를 거쳐 액션 청크 단위로 실행되므로 청크 길이와 인지 노이즈가 움직임을 어떻게 바꾸는지 볼 수 있습니다.
Choose a LIBERO suite and an instructionLIBERO 과제와 지시문을 고릅니다
Press Run VLA Rollout and watch the armRun VLA Rollout을 눌러 로봇팔을 봅니다
Drag to orbit, Ctrl + drag to push an object드래그로 시점 회전, Ctrl + 드래그로 물체 밀기
Purpose연구 목표
Scene interpretation with multimodal physical sensing멀티모달 물리 센싱 기반 장면 해석
We advance human-level visual and physical intelligence through computer vision, deep learning, and multimodal sensor fusion across EO, IR, HSI, SAR, Polarization, Radar, LiDAR, Raman, and RGB-D, developing physics-grounded scene interpretation, remote perception, vision-language-action (VLA) models, world models, and agentic robotics for defense, healthcare, and autonomous physical agents.컴퓨터 비전, 딥러닝, 그리고 다중모달 물리 센싱 융합(EO, IR, HSI, SAR, 편광, 레이더, 라이다, 라만, RGB-D)을 통해 인간 수준의 시각 및 피지컬 지능을 구현하며, 물리 기반 장면 해석과 원격 객체 인지부터 비전-언어-행동(VLA) 모델, 월드 모델, 에이전틱 로보틱스에 이르기까지 국방, 헬스케어, 자율 물리 에이전트를 위한 지능형 시스템을 연구합니다.
The Advanced Visual Intelligence Lab (AVIL) at Yeungnam University bridges physics-driven multimodal perception with neural world models and agentic robotics. We advance Physical Super Intelligence, translating multispectral sensing into autonomous perception and action for defense, healthcare, and robotic systems.영남대학교 지능형시각정보처리연구실(AVIL)은 다중물리 센싱 기반의 시각 인지와 신경망 월드 모델, 에이전틱 로보틱스를 융합 연구합니다. 다중 스펙트럼 센싱을 자율 인지와 제어로 연결하여 국방, 헬스케어, 로봇 시스템을 위한 피지컬 슈퍼 인텔리전스를 구현합니다.
Research areas연구 분야
Computer Vision & Deep Learning컴퓨터 비전 및 딥러닝
Sensor Fusion: EO, IR, SAR, Radar, HSI, Raman, RGB-D센서 융합: EO, IR, SAR, 레이더, HSI, 라만, RGB-D
Robotics: VLA Models, World Models, Agentic Robotics, Embodied Intelligence, Humanoid Robot Intelligence로보틱스: VLA 모델, 월드 모델, 에이전틱 로보틱스, 체화 지능, 휴머노이드 로봇 지능
Applications응용 분야
Intelligent Surveillance지능형 감시
AR/VR
Automatic Target Detection & Recognition자동표적탐지/인식
Physical AI: Autonomous Robots, Drones, Humanoids, Mobile Robots피지컬 AI: 자율 로봇, 드론, 휴머노이드, 이동 로봇
Healthcare헬스케어
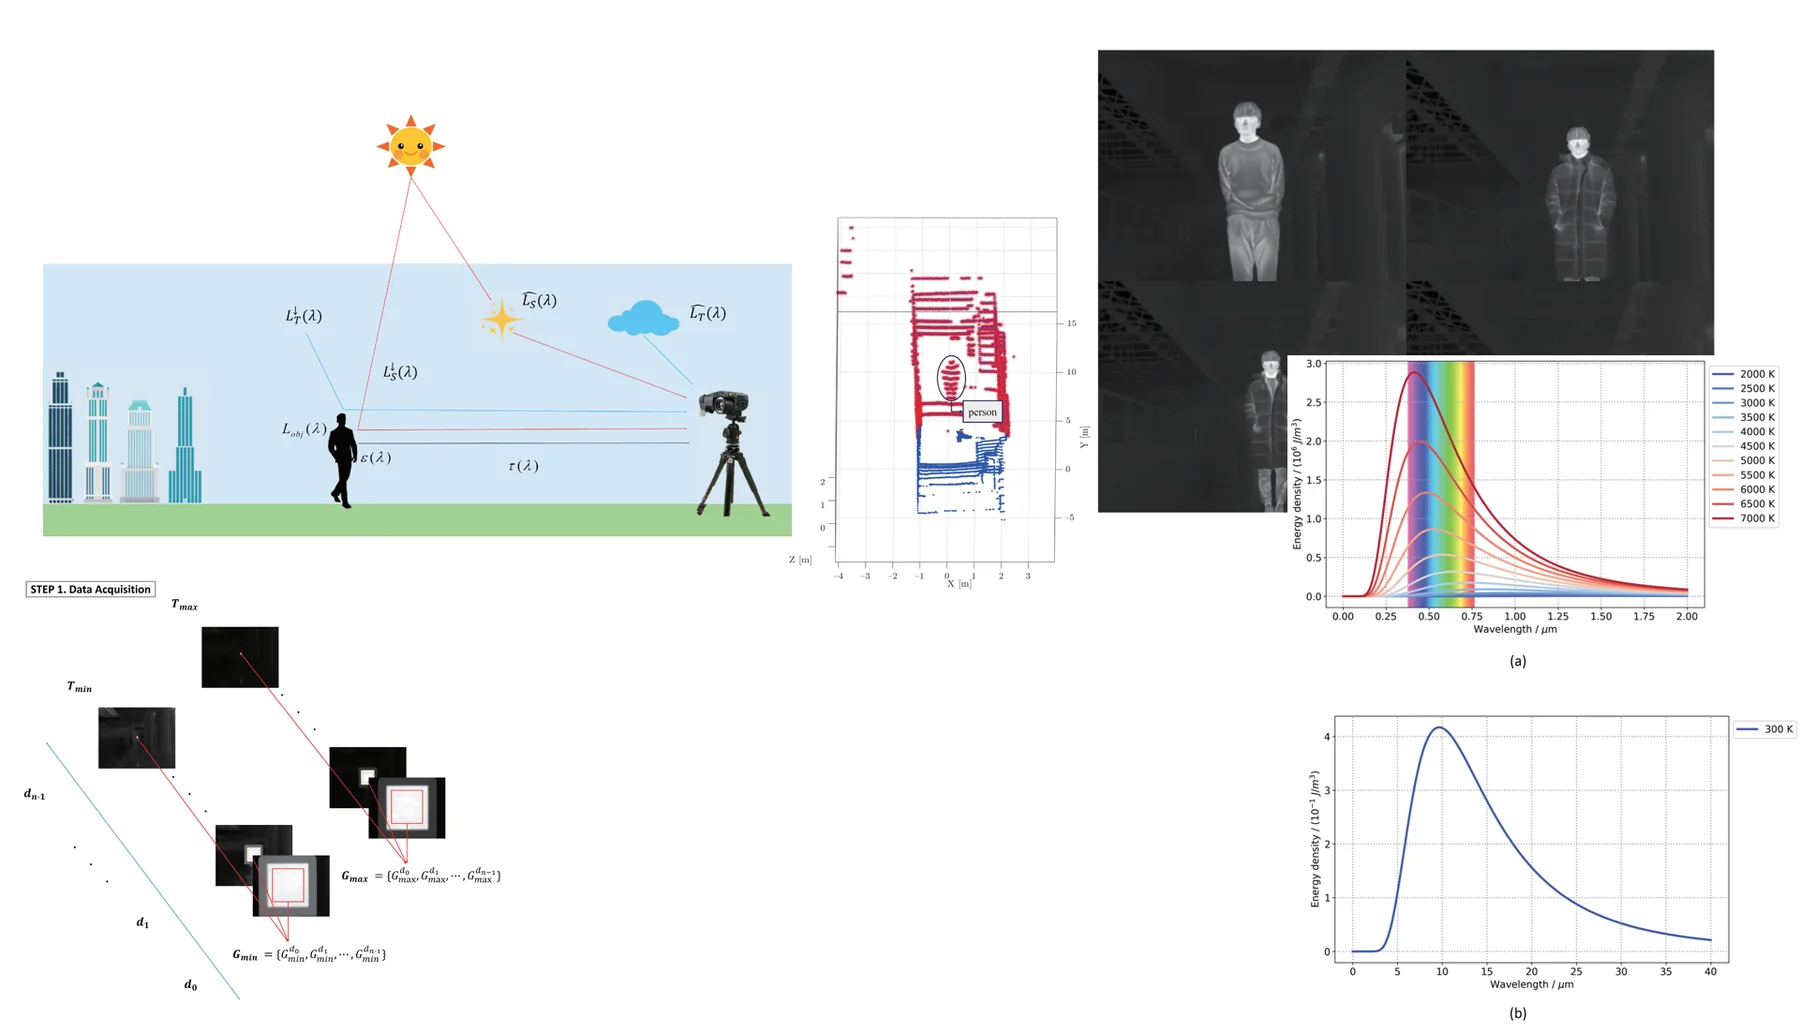
Figures from the lab's work on radiometry, thermal imaging and LiDAR perception.복사 측정, 열영상, 라이다 인식 연구의 그림.
Themes연구 주제
What the team works on now현재 연구 주제
Grouped from the research areas members list, with the papers that match each theme.구성원의 연구 분야를 주제별로 묶고, 관련 논문을 함께 보여줍니다.
Physical AI & Embodied Intelligence피지컬 AI 및 체화 지능
27papers논문4members구성원
Recent papers최근 논문
2026 GaussVLA: Geometry-Aware Spatial Reasoning for Vision-Language-Action Model
2026 Structured Gaussian Spatial Tokens for 3D Depth-Aware Vision-Language-Action Models
2026 A Review of EO-Based Object Perception and Radar-Assisted Range Compensation for Robust Robotic Grasping in...